Available for data science & ML opportunities

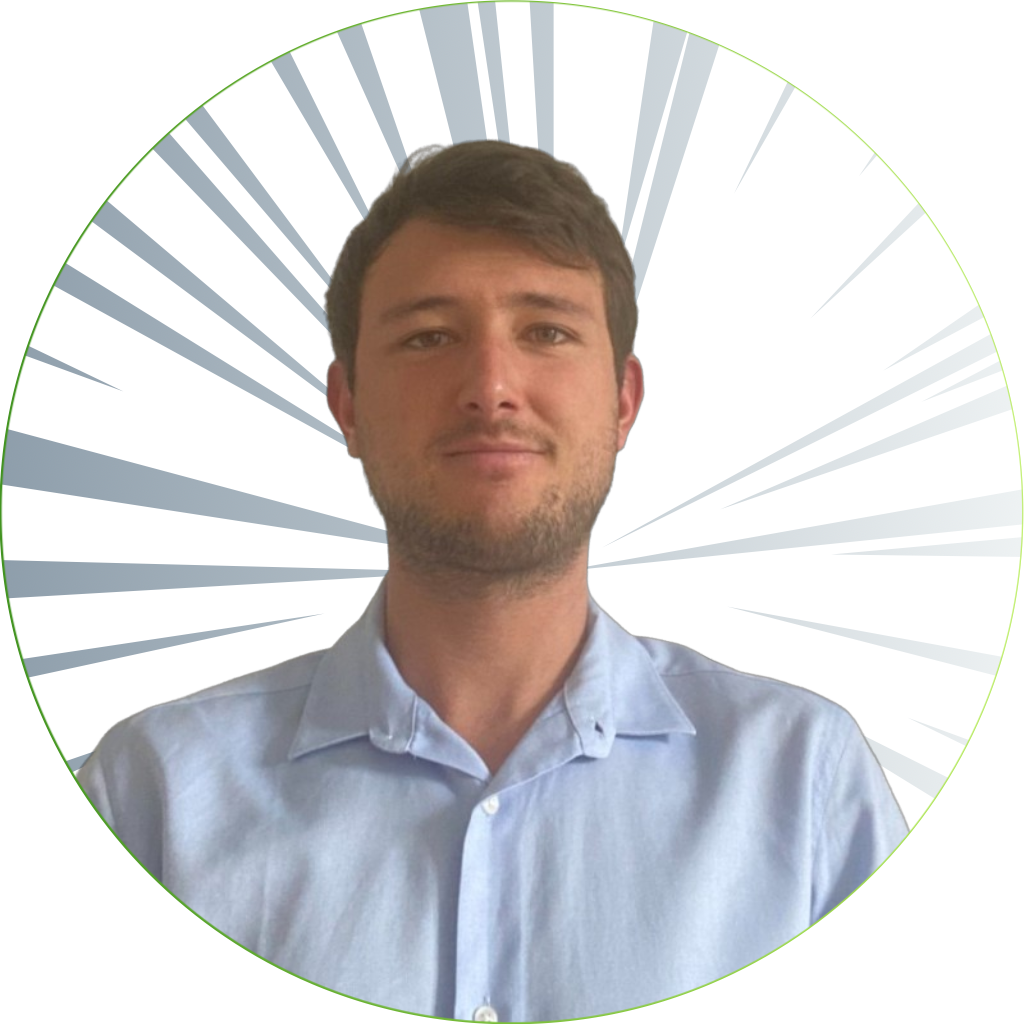
Hi, I'm Bruno Stordeur

I am a Data |

I use machine learning and data science to solve complex problems and improve processes — from exploration and modeling to deploying models into production. Strong background in mathematics and computer science, with a growing focus on MLOps. Together, let's harness your data.

About

Turning data into decisions

I'm a Data Scientist & ML Engineer based in Paris, with a strong background in applied mathematics and computer science. Over the past few years I've delivered data and ML projects across banking, healthcare and payments — from fraud scoring and operational-risk analysis to synthetic time-series generation and clinical event prediction.

I like owning the full lifecycle: exploring and cleaning data, engineering features, building machine learning and deep learning models, and shipping them to production with solid MLOps practices — testing, CI/CD, containers and monitoring.

Outside of work, I build ambitious side projects — an automated crypto trading system and a large-scale ML research platform — to keep sharpening my data engineering and applied-ML skills.
4+
Years in data & ML
2
MSc — Data Science & Applied Maths
5
Professional certifications
3
Industries: banking, health, payments
Experience

Where I've worked

Data science & analytics roles across payments, healthcare and banking.

Cartes Bancaires

Mar 2024 – Mar 2025 · Paris
Data Scientist — Freelance

Scoring & fraud detection on EPI (Wero) transactions

The European Payment Initiative (EPI) and its Wero wallet aim to build a unified pan-European payment system. In this context, fraud prevention and detection are essential to ensure security and trust in these new payment methods.

Responsibilities
  • Defined a data catalog to structure P2P and e/m-commerce data, and helped integrate new catalogs into existing systems.
  • Created "cold start" rules to address the absence of initial data.
  • Monitored activity and scoring during the launch on IBM Safer Payments.
  • Explored and analyzed data, and developed new scoring rules using ML models and banks' fraud feedback.
  • Conducted technology watch and presented articles on the subject.
  • Python
  • SQL
  • PySpark
  • IBM Safer Payments
  • Apache Zeppelin
  • Hue

CHU de Brest

May 2023 – Nov 2023 · Paris
Data Scientist

Synthetic temporal data & prediction of intracranial hypertension events

Explored how machine learning and deep learning can help physicians make better treatment decisions for intracranial hypertension: generating high-quality synthetic data, predicting arterial and intracranial pressure, and predicting hypertension events.

Responsibilities
  • Conducted a technology watch and synthesized the state of the art.
  • Used a deep learning model (DGAN) to generate synthetic data, with DTW metrics to filter its quality.
  • Handled data extraction, cleaning, preparation and feature engineering.
  • Performed step-by-step prediction with deep learning and binary classification with ML models.
  • Python
  • TensorFlow
  • Keras
  • Sklearn
  • Pandas
  • Docker

BNP Paribas

Oct 2022 – Apr 2023 · Paris
Data Analyst

Historical incident analysis — Risk ORM

Within the Risk ORM division, operational risk management is crucial to monitor and mitigate risks across all banking activities. Analyzing historical incidents helps identify areas of vulnerability.

Responsibilities
  • Analyzed and explored data from historical incidents.
  • Ran correlation analysis between incidents, causes, risk types and failing business units to spot high-risk areas.
  • Cross-referenced incidents with implemented controls to determine at-risk perimeters.
  • Simplified and presented the results.
  • Dataiku
  • Python
  • SQL

Digitrips

Sep 2021 – Sep 2022 · Paris
Data Scientist

Cache optimization & flight-booking prediction

Flight bookings were systematically cached regardless of relevance, causing significant cost and latency. I worked on two parallel projects: classifying the relevance of flight searches to free up cache, and forecasting future flight bookings.

Responsibilities
  • Extracted data from SQL databases; ran analysis, exploration, feature engineering and selection.
  • Trained and optimized machine learning / deep learning models.
  • Built time-series forecasts for flight bookings (ARIMA, SARIMA, LSTM).
  • Simplified and presented the results.
  • Python
  • SQL
  • TensorFlow
  • Keras
  • ARIMA / LSTM
Projects

Things I've built

A mix of ambitious personal systems and end-to-end ML projects. The first two are original work I designed and built from scratch.

Flagship

KrakenBot — Automated BTC Trading

A production-grade automated trading system for the Kraken exchange, built as two independent 24/7 services with real-time market data ingestion, a multi-strategy engine and built-in risk management — deployed to a VPS via CI/CD.

  • Python · asyncio
  • PostgreSQL / TimescaleDB
  • Dash
  • Docker
  • GitHub Actions
Original

Solana Memecoin ML Platform

An ML research platform analyzing 30,000+ Solana memecoins to discover behavioral archetypes and predict short-horizon price moves from the first minutes of trading — with rigorous, leakage-safe time-series methodology (walk-forward CV, per-token scaling).

  • Polars
  • PyTorch · LSTM
  • LightGBM
  • XGBoost
  • Streamlit

Student Performance — Azure Deployment

An end-to-end ML regression app (predicting student exam scores) packaged with Docker and deployed to Azure — pushed to Azure Container Registry, served as an Azure Web App, with GitHub Actions handling continuous deployment. The focus here is the deployment pipeline.

  • Docker
  • Azure
  • GitHub Actions
  • Flask
  • scikit-learn

Kidney Disease Classification

An end-to-end deep-learning pipeline classifying kidney CT scans, with experiment tracking (MLflow / DagsHub), data & pipeline versioning (DVC), and a Flask prediction app — a complete, reproducible MLOps template.

  • TensorFlow / Keras
  • MLflow
  • DVC
  • Flask

ML Pipeline with ZenML

A production-style ML pipeline predicting customer-satisfaction scores on the Olist e-commerce dataset, with continuous training/deployment (accuracy-gated), MLflow tracking and a Streamlit app consuming the live model service.

  • ZenML
  • MLflow
  • scikit-learn
  • Streamlit

SQL Spaced-Repetition Trainer

A spaced-repetition web app to practice SQL queries against a DuckDB engine, checking your answer against the expected result, with a GitHub Actions code-quality CI pipeline — a self-directed tool for keeping SQL sharp.

  • Python
  • DuckDB
  • Streamlit
  • GitHub Actions
Skills

Tools & technologies

The stack I use across data engineering, machine learning and MLOps.

Languages

  • Python
  • SQL
  • Shell
  • HTML5
  • CSS3

Data Manipulation

  • SQL
  • BigQuery
  • Spark
  • Pandas
  • NumPy

Machine Learning

  • scikit-learn
  • Keras
  • TensorFlow
  • MLflow

Cloud

  • Azure
  • AWS
  • Google Cloud

Data Visualization

  • Matplotlib
  • Seaborn
  • Plotly

Testing & Quality

  • Pytest
  • Black

API & Web

  • FastAPI
  • Flask
  • Streamlit

Orchestration

  • Airflow
  • Metaflow

Version Control & DevOps

  • GitHub
  • GitHub Actions
  • Poetry
  • Docker
  • DVC
Certifications

Certifications

Microsoft Certified: Azure AI Engineer Associate
Dataiku certifications
Dataiku: Advanced Designer, ML Practitioner, MLOps
Machine Learning — Stanford
Machine Learning — Stanford University
Data Upskilling
Data Upskilling — Benjamin Dubreu
Developer Security Champion
Developer Security Champion — Aroua Biri
Education

Education

MSc Data Science & Business Analytics

EDC Paris Business School

MSc Applied Mathematics & Statistics — Data Science

Aix-Marseille University

Contact

Let's harness your data

Open to data science & ML opportunities and collaborations. The fastest way to reach me is email.